
OpenAI and Google Plan One AI Training Opt-Out While Search Stays Open
On this page 6 sections
AI-generated editorial illustration.
On October 30, a publisher checking its robots.txt file saw two promises with different clocks.
OpenAI said it would honor a shared signal
for generative AI training in the coming months.
Google said it planned support in 2027. The
signal begins with User-Agent: __usage_ai-training and uses ordinary path rules. One file could eventually state a
training preference to several providers.
The announcement did not switch on an industry standard overnight. Its underlying October 30 Internet-Draft is an individual proposal by Anthropic’s Kevin Kelley, published through the IETF process. The IETF’s own record says it has no formal standing as an approved standard. OpenAI gave no exact implementation date. Google described a plan for 2027. A publisher editing the new line today cannot assume every crawler has changed its behavior.
The publisher has to make today’s choice with today’s tools. It wants people to find an article through search and
perhaps through an AI answer. It may also want to sell a training license. A Disallow rule aimed at every crawler can
sacrifice discovery; an open door to discovery does not settle training rights or payment. The new signal separates one
use of the work from the act of fetching it. It leaves the price blank.
A site editor can ask the search lead for a list of pages that must remain discoverable. The licensing lead may return a different list of pages that can be sold for training. The two lists will overlap, and neither person can resolve the overlap by changing one bot rule. The draft supplies a way to state a training preference. Search access, answer appearance and payment still need their own controls and records.
October 30 produced a promise, not a switch
OpenAI’s announcement is short. It says a common signal would reduce the work of naming and maintaining separate crawler
rules for each participating provider. Its existing robots.txt controls continue. The company intends to implement the
shared signal in the coming months and provide more detail then. It does not publish a rollout percentage, a testing
receipt for any publisher or a promise that a training exclusion will generate traffic.
Google’s announcement sets a later date and describes a particular interaction with its own control. If a site opts out
through the new policy token and does not explicitly specify Google-Extended, Google plans to interpret the signal
as if Google-Extended were disallowed. If the site does specify Google-Extended, that vendor-specific instruction
can express a different choice. Google says its support is planned for 2027. That is a stated future interpretation, not
evidence that its crawler applies the new token today.
John Mueller, Google’s Search Advocate, signed the Google post. The detail about Google-Extended is the part a
publisher cannot skip. A generic opt-out may preserve ordinary Google Search while changing eligibility for Gemini
grounding. A publisher that relies on referrals from both products needs to decide whether those channels deserve the
same policy. Google’s announcement describes that choice; it does not forecast how many visits either route would send.
A search team would have to measure that on the site’s own pages after implementation.
Kevin Kelley works at Anthropic, and the draft’s acknowledgments name participants from publishers, technology companies and civil society. Those affiliations do not turn his individual draft into an Anthropic product announcement or IETF consensus. An editor writing a policy this week faces a simpler fact: a draft can change, and neither provider has switched on its announced support. Existing bot controls remain the operative published instructions until a provider documents and demonstrates the new behavior.
A public robots.txt line can prove what the site declared on a date. It cannot prove what a model developer collected
months earlier, whether a mixed-purpose crawler retained data for a later use, or whether a dataset provider passed a
restriction along. A newsroom that adds the line should record the date and the served file. It should not report that
training stopped. That claim requires evidence the public file cannot provide.
One token describes a use, not a visitor
The draft text uses the
familiar robots.txt structure. Its example places User-Agent: __usage_ai-training above Disallow: / and then
Allow: /press-kit/. Under that example, a service operator expresses a preference against generative AI training for
the site except the press-kit path. The Allow and Disallow syntax does not change. The new item is the purpose token
in the user-agent position.
That position is easy to misread. The policy token does not have to appear in the HTTP request’s user-agent header. It
is a key a participating provider uses when interpreting the file. A site’s access logs might therefore show Googlebot
or another real crawler, while the use preference sits in a separate policy group. Looking for __usage_ai-training as
though it were a visiting bot would miss the point.
The draft defines the covered use as using an asset to modify the learned parameters of a generative AI model. It explicitly leaves exclusively non-generative classification, ranking and scoring outside that category. It does not claim to decide whether a particular answer’s retrieval, quotation, or display is training. A policy against one use cannot be read as a universal veto over every kind of AI processing.
That narrow definition can be useful even to a publisher that does not want a total block. A job board might want its public listings found by a search service while keeping proprietary descriptions out of model training. A software company may want freely available documentation retrieved in answers but reserve a paid training corpus. These are possible policy choices, not accounts of named companies changing their files. The policy has to follow the rights in the actual work. A site that states a training preference for content it merely hosts under license may be declaring a choice the underlying rights holder never made.
The text also says wildcard User-Agent: * groups must not be treated as matching the policy token. No group with the
new token means no preference expressed through this mechanism. That is not a statement that every use is
authorized. Other terms, laws and vendor-specific signals may still matter. The draft treats crawler access rules and
content-use preferences as separate. A provider may choose not to fetch a page it cannot train on, but the token itself
is not an instruction requiring it to stop crawling.
The draft leaves precedence partly in the consumer’s hands. More specific expressions should generally outrank broad
ones, it says, and a provider may document that its own token is more specific than the shared signal. A private
agreement may also override a public preference. Those qualifications make a site-wide copy-and-paste recipe risky. An
operator with a Google-Extended rule or a direct data license must read the contract and the provider’s interpretation
together. Fewer lines in the file do not mean fewer decisions.
For a site with multiple rights holders, path rules are useful only if the URL structure follows the rights map. A publisher might control its original reporting but license syndicated photographs under different terms. If both assets appear under a common path, a single broad rule might misstate the rights it can grant or reserve. The draft’s path example makes the need for an inventory visible. It does not do that inventory for the operator.
Search access already has separate controls
OpenAI’s crawler documentation distinguishes GPTBot, associated with
training its generative models, from OAI-SearchBot, used to surface sites in ChatGPT search. It says their settings
are independent. A site can disallow GPTBot while allowing OAI-SearchBot. It also says it may reuse the result of one
crawl for both uses when both are allowed, to avoid duplicate fetching. The distinction is about permitted use, not
necessarily the number of HTTP requests an operator will see.
OpenAI says a site blocked from OAI-SearchBot will not be shown in ChatGPT search answers, although navigational links
can still appear. Its documentation cautions that changes to robots.txt can take roughly 24 hours to affect search
systems. Those details make an audit more concrete: check the file served publicly, check the search bot’s access, and
wait for the documented processing interval before treating a missing answer as evidence of a fault. Even then,
permission to appear is not a guarantee of a citation or a click.
Google’s crawler documentation
places Google-Extended in a different category again. It is a robots.txt product token, not a separate HTTP request
user agent. Google uses it to control whether content it crawls can train future Gemini models and be used for grounding
in Gemini Apps and Grounding with Google Search on Vertex AI. Google says Google-Extended does not affect inclusion or
ranking in Google Search. Its October 30 announcement adds a commercial complication: a site that specifically allows
Google-Extended remains eligible to appear in Gemini Apps responses and receive clicks through grounding. A site
considering an opt-out should therefore separate ordinary Google Search from Gemini grounding instead of treating both
as one visibility channel.
The documents expose two common mistakes. Blocking Googlebot to stop model training would change ordinary Google Search
access, even though Google provides Google-Extended for a different purpose. Blocking OAI-SearchBot to stop OpenAI
model training would change ChatGPT search eligibility, even though GPTBot is the training control in OpenAI’s current
documentation. Neither mistake requires a sophisticated attack. It can arise when a team maintains one spreadsheet
column marked “AI bot” and maps every crawler to the same action. The new token helps only if the spreadsheet gains a
separate column for the use of fetched content.
Neither provider’s documentation promises a publisher the same traffic after changing a rule. The decision is about eligibility and permitted use; actual referrals depend on queries, product behavior, ranking and whether an answer sends someone onward. A publisher that wants to preserve discovery should monitor search indexing, AI answer referrals and training preferences as three separate series. Counting crawler requests alone would not resolve the question.
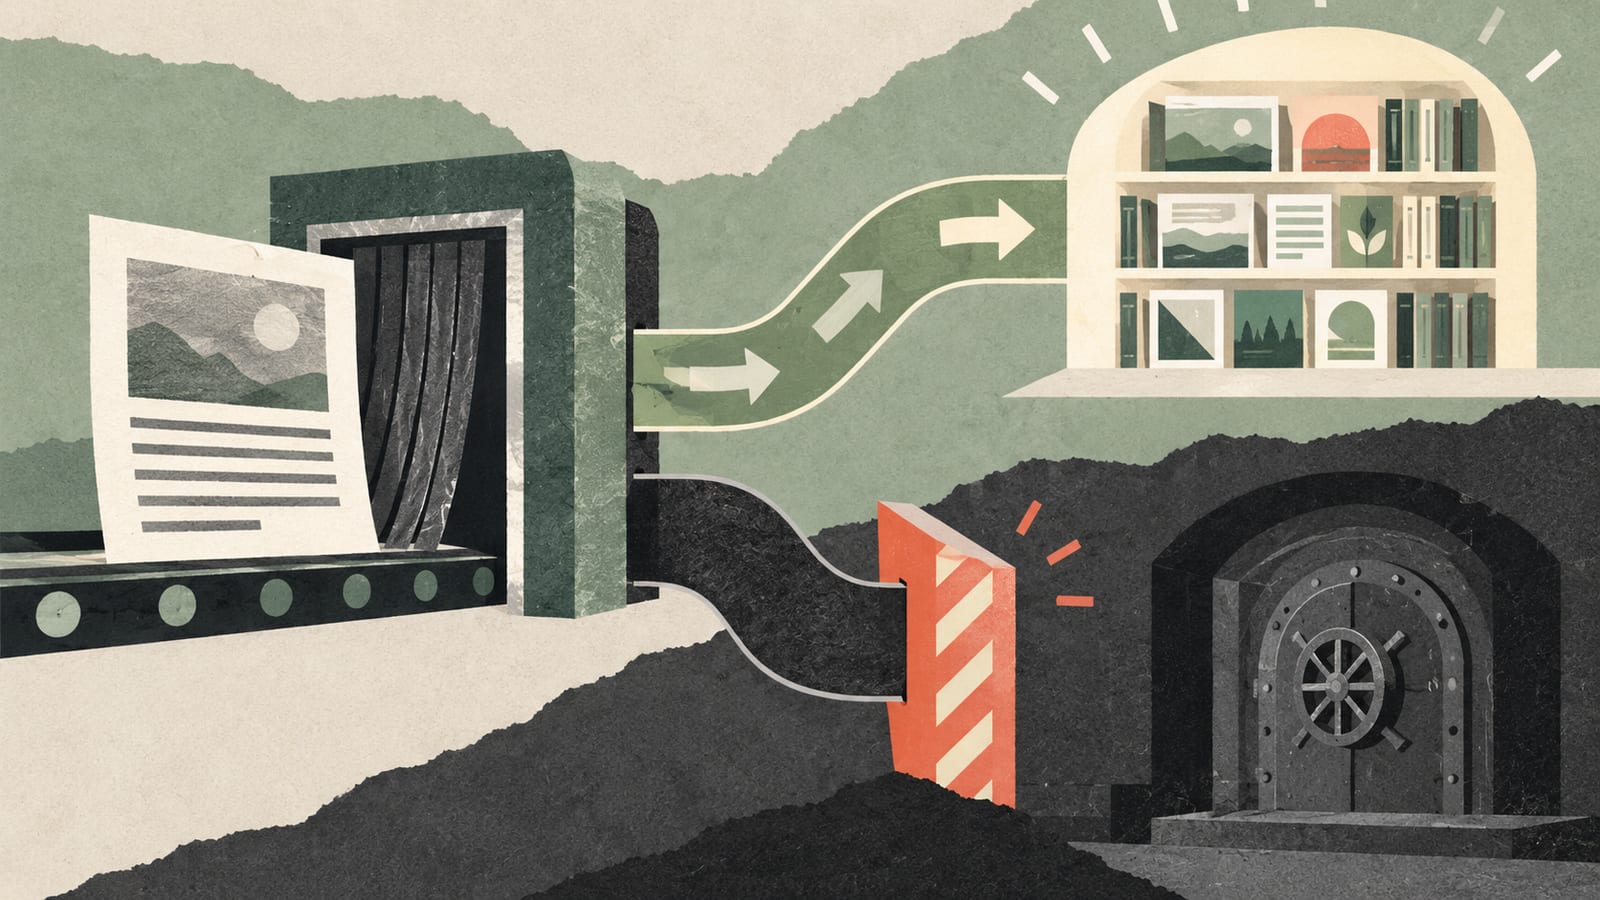
AI-generated editorial illustration. The routes represent separate search access and training-use decisions.
The economic bargain remains unsettled
The new token has appeal because the old arrangement requires a growing list of named bots. The
International Press Telecommunications Council’s March guidance
describes several opt-out techniques already in use, including robots.txt, licensing and other rights signals. Its
advice is a reminder that publishers cannot simply rely on one syntax for every provider and every asset. A shared
signal could shrink maintenance work if adoption becomes broad. It cannot retroactively reconcile every older contract.
IPTC’s updated guidance appeared seven months before the new individual draft. It added Really Simple Licensing and Cloudflare’s Content Signals to an already crowded set of techniques. That history matters to an editor maintaining a live site: content has been published, crawled, syndicated and licensed under earlier rules. A new policy line applies to the served file going forward according to the draft’s model. It cannot tell a publisher which historical copies sit in a model provider’s archives or whether a syndication partner kept the rights metadata attached. The immediate work is to identify what the publisher controls at its own host and what requires a conversation with partners.
Cloudflare has put a number on the mixed-use problem, with an important denominator. In a September 15 release, it said crawlers that gather content for both search indexing and AI training represented 36.6% of verified crawler traffic on its network. It also said fewer than 1% of website owners blocked search crawlers while 17% restricted AI training. These are Cloudflare network and customer observations, not a census of the whole web. They show why a binary block-or-allow choice is costly for publishers: many want discovery and a different training policy at the same time.
Cloudflare’s answer includes an AI training control that it says can keep a site indexed while refusing training use by accountable mixed-purpose crawlers. It also launched a Pay Per Use beta in which an AI buyer proposes a price for a specified use and reports uses for billing. That beta requires a buyer, an accepted offer and self-reported usage checked against enrolled publishers. A shared training opt-out does none of those things. It states a preference against a use; it does not establish a license, a price, a reporting obligation or a payment claim.
Cloudflare’s 36.6% measures verified crawler traffic on its network, not human visits, ad revenue or training datasets. Its 17% counts sites restricting training, not content excluded. The under 1% search-block figure is another website choice. Plotting the three numbers as though they share a denominator would distort the story. Read with their denominators attached, they show operators more willing to refuse training than to disappear from search.
Cloudflare’s commercial proposal addresses a different hole in the new draft. In the beta, buyers specify the use they will pay for and publishers accept an offer. Usage is reported by the buyer, then checked against enrolled publishers before billing, according to Cloudflare’s description. That is a transaction design with a price and a reporting path, although its performance is not established by the launch post. The shared token has no field for a rate per article, a definition of payable use in an answer, or a remedy if a buyer does not report one. A publisher seeking compensation still needs a contract or payment system, and a review of its rights to sell that use.
A provider could interpret separate training and search controls precisely and continue sending people to useful pages. A publisher could allow training for freely reusable documentation and restrict a paid archive. The value of that arrangement would have to show up somewhere beyond the public file: in organic search clicks, AI referrals, crawler access or licensing receipts. Those measures need a baseline and a review after the provider actually supports the token.
The rights question is wider than robots.txt. The
European Commission’s guidance on general-purpose AI obligations
says model providers must maintain a policy to comply with Union copyright law and take measures to identify and respect
rights reservations. Google argues the new signal is consistent with the voluntary general-purpose AI Code of Practice.
That regulatory context explains why machine-readable declarations matter, but it does not turn this particular
individual draft into a legal command or decide a dispute about an individual work. Contracts, jurisdiction and the use
of a given asset still matter.
Sort rights by page before writing rules
Begin with the work being published, not the name of the crawler. A newsroom may control its original articles and merely display licensed images. It may publish a press release freely but reserve a member archive. Each class asks for a separate rights decision. The table below is an operating worksheet, not a universal robots.txt configuration. Each rule needs a rights review and a live test against the provider’s current documentation.
| Question for a page class | Present control or record | What the new token could add | What the result cannot prove |
|---|---|---|---|
| Should Google Search index this page? | Googlebot access, index directives, sitemap and Search Console | Nothing directly; the draft concerns training use | A training rule does not guarantee ranking or clicks |
| Should ChatGPT search surface it? | OAI-SearchBot access and referral measurement | Nothing directly; OpenAI keeps current crawler controls | An allowed search bot does not guarantee citation |
| May OpenAI use it for model training? | GPTBot rule, contract and content-rights inventory | A common use preference once OpenAI implements it | A declaration alone does not show dataset removal |
| May Google use it for model training or Gemini grounding? | Google-Extended, explicit rights agreements and product reporting | Google plans a default interpretation in 2027 when no specific Google-Extended choice is present | A Google Search result does not show Gemini use or non-use |
| May another AI buyer pay for a defined use? | Negotiated or platform licensing terms and usage receipts | No price term; the token can inform a separate negotiation | An opt-out is not a payment mechanism |
The table separates crawl access, content use, appearance and compensation. Those are different fields in an operator’s decision, even when one provider collects a page only once. The new token makes one field easier to communicate. It does not merge the others into a complete contract.
A rights inventory also prevents an accidental overstatement. Who owns a commissioned photo? Is a wire-service paragraph licensed only for display? Do contributors retain training rights? Does a paywall cover the same asset as the public excerpt? If the answers differ, the site’s path-level rules and contracts need to reflect the differences. A technical rule written at the root of a site can be broader than the rights the site holds.
Consider an illustrative scenario, not a reported meeting or customer case. A regional publisher places original
stories at /news/, agency photos under /images/, public event notices at /events/ and paid data at /research/.
The editor wants the news articles visible in Google Search and ChatGPT search. The photo agreement permits display but
does not spell out model training. The research subscription contract reserves reuse. One root-level Disallow for
every AI-associated bot would be easy to type and hard to defend: it might close search routes the editor wants, while
saying nothing precise about the photo contract. A purpose group with path rules could state a narrower training
preference once participating providers support it. The team would still need separate crawler access rules and the
rights owner’s approval for the photo and data classes.
There is no public measurement that can tell this hypothetical publisher the perfect rule beforehand. If the search team
sees few AI referrals today, it may make a different business choice from a site receiving many qualified subscribers
from answer engines. If a provider offers a paid training license, the contract’s value depends on the covered material,
term, reporting and enforcement, none of which fit in a User-Agent line. A single default across all publishers would
hide those differences. The matrix keeps them visible at the decision meeting.
What can be verified now
An operator can perform several checks without waiting for 2027. First, record the current public robots.txt response
for each hostname and verify that it is reachable. Second, list the crawler-specific rules already in force, including
GPTBot, OAI-SearchBot, Googlebot and Google-Extended, and compare them with the site’s stated editorial and
commercial policy. Third, identify the path classes whose rights differ. Fourth, capture current search and referral
baselines with the same properties and windows, and preserve any license receipts separately. These are present-tense
checks, not proof of future compliance.
The new token can then be evaluated as a proposed addition. The draft says an explicit policy group is required; a wildcard group does not carry the new preference. The file should be tested for the paths it means to cover. A provider’s published implementation note should be checked before the site treats the token as operative for that provider. If a company-specific rule is intended to override the shared choice, document that choice explicitly and recheck the provider’s precedence rules. The draft says specific expressions should generally take precedence and private agreements may override preferences, but the service operator still has to know what it agreed to.
The last check is an outcome check with honest limits. Server logs can show requests from identifiable crawlers. Search Console can show search indexing, impressions and clicks for the canonical property. Analytics can show referred visits when tracking is present. A licensing ledger can show agreed payments. None of these sources can fully observe a model developer’s internal training set or prove that a particular paragraph never influenced a model. An operator should label that evidence gap instead of filling it with a crawler count.
A preference file may be changed on Tuesday, while a provider’s support begins months later and a search index updates on its own schedule. A fall in visits on Wednesday would not establish that the training rule caused it. A rise in referrals would not establish that the provider honored a training restriction. Keep the dates of the file change, provider implementation, crawl observations and traffic windows next to each other. Then a publisher can ask a narrower question: did the search route remain eligible after the policy change, and did the provider say it interpreted the training signal for the relevant paths? That is a checkable operating result, even though it falls short of an audit of model weights.
The publisher’s next robots.txt review should therefore have two dates beside it: October 30 for the announcements,
and a blank space for each provider’s actual implementation. Until those spaces are filled, the current bot rules and
contracts carry the decision.